Under the Hood: The RUM Conjecture
Formulated by researchers Manos Athanassoulis and Stratos Idreos at Harvard, the RUM Conjecture describes a lower-bound tradeoff among read overhead, update overhead, and memory overhead: reducing one usually consumes more of at least one other resource. It is a design lens, not a rule that every engine cleanly optimizes exactly two:
- R (Read Amplification): The ratio of bytes read from physical storage to the bytes returned to the application. High read amplification means multiple disk blocks must be read to satisfy a single point or range query.
- U (Update / Write Amplification): The ratio of bytes written to physical storage to the bytes updated by the application. High write amplification exhausts disk bandwidth and accelerates SSD wear.
- M (Memory Overhead): The auxiliary in-memory state required by the access method, such as indexes, filters, and routing metadata. Disk-space amplification is a related operational metric, but it is not the M in the RUM formulation.
The RUM Tradeoff Frontier
flowchart TD
Tradeoff{"Storage Engine Architecture"}
Tradeoff -->|"B+ Tree (InnoDB / Postgres)"| BTree["Optimize Read & Space Amplification (1-2 disk reads, 1.2x space) at the cost of high Write Amplification (10x-50x 16KB page rewrites)"]
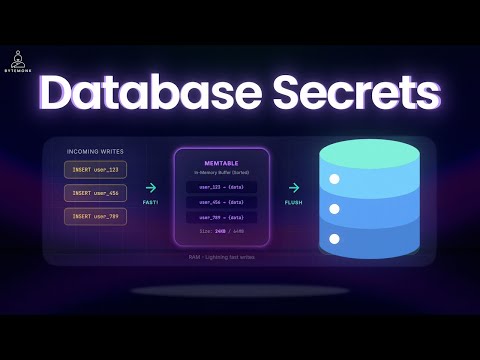
Tradeoff -->|"LSM Tree (RocksDB / Cassandra)"| LSM["Optimize Write Amplification (sequential appends) at the cost of high Read Amplification (multi-SSTable scans) and Space Amplification (compaction debt)"]
Tradeoff -->|"Fractal Tree / B-epsilon Tree"| Fractal["Balanced compromise: Buffer messages in internal tree nodes to trade write I/O for tree depth"]
Detailed Comparison: B+ Trees vs LSM Trees
| Dimension | B+ Tree Storage Engine | LSM-Tree Storage Engine |
|---|---|---|
| Write Pattern | In-place update of 8KB/16KB pages on disk | Sequential append to WAL + memory buffer |
| Point Read Latency | Fast: O(log_B N), typically 2-3 page reads from cache | Slower: Requires checking memtable, bloom filters, and multiple SSTables |
| Write Throughput | Moderate: Limited by random I/O and locking page latches | High: bursts are limited by sequential bandwidth, but sustained throughput is bounded by compaction bandwidth (engines stall writes when compaction falls behind) |
| Write Amplification Factor | Often high and workload-dependent: a 50-byte update can dirty a full 16KB page, though buffer pools absorb many updates per page flush | Moderate: roughly 10x-30x for leveled compaction, lower (often under 10x) for tiered compaction |
| Space Utilization | Moderate: after random inserts pages average about 69% full (about 30% free space) because of page splits | High: Sorted keys allow dense prefix compression (ZSTD / Snappy) |