Case: Instagram's First Architecture
Instagram's early scaling work is legendary because it was achieved by an incredibly small team. It separated three jobs that appear together on a phone: running application code, retrieving records, and delivering image bytes. Its engineers' 2011 posts and Mike Krieger's 2012 talk let us follow those choices.
When Instagram launched in 2010, they grew from 0 to 1 million users in just a few months, with only a handful of engineers. They couldn't afford complex microservices; they needed extreme simplicity and reliable off-the-shelf tools.
The Core Stack: Keep It Simple
The original architecture was built entirely on Amazon Web Services (AWS) using technologies that were boring and predictable:
- OS: Ubuntu Linux
- Load Balancing: Amazon Elastic Load Balancer (ELB) routing requests to Nginx.
- Application Server: Django running on Python with Gunicorn.
- Data Store: PostgreSQL for user data and metadata, Redis for feeds and sessions, Memcached for caching.
- Storage: Amazon S3 for photos, CloudFront for CDN.
Scaling the Database: Sharding IDs
The most fascinating part of early Instagram was how they scaled PostgreSQL. As they grew rapidly, a single database could no longer hold all the data or handle the read/write volume.
They needed to partition (shard) the data across multiple database instances. But this introduced a problem: how do you generate unique IDs for photos when you don't have a single central database keeping track of the auto-incrementing primary key?
Their solution was brilliant and simple. They created a custom ID generation scheme using PL/pgSQL directly inside the database shards. The 64-bit ID consisted of:
- 41 bits for time in milliseconds (about 69.7 years from the chosen custom epoch).
- 13 bits that represent the logical shard ID.
- 10 bits that represent an auto-incrementing sequence, local to each schema (modulo 1024).
This allowed the application to route a request directly to the correct shard just by inspecting the photo ID, without needing a per-ID lookup table to find where the photo lived; a small map from logical shards to physical servers completes the routing.
Storing the Feed in Redis
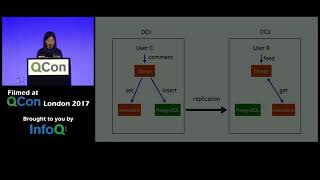
To serve the home feed quickly, Instagram heavily utilized Redis. Whenever someone posted a photo, the photo ID was pushed into the Redis lists of all their followers. Because Redis keeps all data in memory, pulling a user's feed was instantaneous.
To save memory, they didn't store full JSON objects in Redis, only the photo IDs. The application would fetch the IDs from Redis, and then do a quick SELECT IN query against PostgreSQL to get the photo metadata (like caption and author).
Worked example: building and decoding an Instagram ID
Layout: 41 bits of milliseconds since a custom epoch, 13 bits of logical shard id, 10 bits of per-shard sequence.
- Time since epoch: 1,000,000,000 ms (about 11.6 days).
- Logical shard: 1341 (13 bits allows 8,192 logical shards).
- Sequence: the shard's sequence returns 5001, and 5001 mod 1024 = 905.
ID = (1,000,000,000 shifted left by 23) OR (1341 shifted left by 10) OR 905 = 8,388,608,000,000,000 + 1,373,184 + 905 = 8388608001374089. Decoding: shift right by 23 to recover the timestamp; shift right by 10 and mask with 8191 to recover shard 1341. The application then looks up which physical PostgreSQL server currently hosts logical shard 1341.
Limits: 1,024 IDs per shard per millisecond, and 41 bits of milliseconds last about 69.7 years from the chosen epoch.
The alternatives Instagram rejected
| Option | Pros | Cons for Instagram |
|---|---|---|
| UUIDs | No coordination | 128 bits; not time sortable; poor index locality |
| Twitter Snowflake service | Time sortable 64-bit IDs | Another service to run (and ZooKeeper) for a tiny team |
| Ticket database (Flickr style) | Simple | A single write bottleneck and point of failure |
| PL/pgSQL function in each shard schema | No new service; time sortable; shard embedded | Relies on per-shard sequences and reasonably synced clocks |
Why logical shards matter
Instagram created thousands of logical shards as PostgreSQL schemas and placed many on each physical server. Moving load meant moving whole schemas to a new server (for example by promoting a replica) and updating the logical-to-physical map, without ever re-hashing a single ID. This is the same "many more partitions than nodes" idea used by Cassandra vnodes and Kafka partitions.
Feed storage trade-off
Pushing each new photo id into every follower's Redis list (fan-out on write) makes reading a feed a single list read plus a batched metadata lookup, but a user with millions of followers turns one post into millions of writes. Large systems eventually mix fan-out on write for most users with fan-out on read for very high follower counts.