Understanding Nearby Geospatial Search
Geospatial search is a core component of many modern applications, from ride-sharing services like Uber to review platforms like Yelp. At its core, the problem is about finding points of interest (POIs) that are physically close to a user's current location within a given radius.
The Naive Approach
A naive approach might involve storing the latitude and longitude of every POI in a relational database and calculating the distance between the user and every POI on the fly. You could use the Haversine formula for this:
SELECT * FROM places WHERE haversine(lat, lon, user_lat, user_lon) < radius;However, this requires a full table scan, computing a complex trigonometric function for millions of rows. It is highly inefficient and will not scale.
Spatial Indexing
To optimize this, we need spatial indexing. The fundamental idea of spatial indexing is to map two-dimensional coordinates (latitude and longitude) into one-dimensional strings or numbers, which can then be efficiently indexed by standard databases (using B-Trees, for example). Common strategies include:
- Geohash: Divides the world into a grid of rectangles, assigning a string to each.
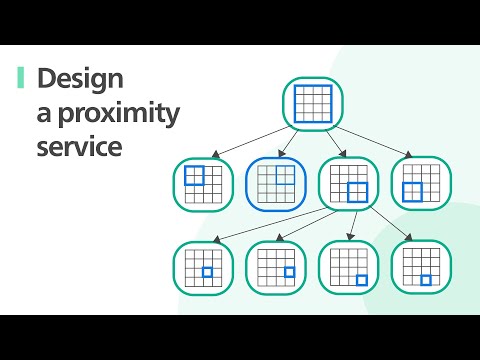
- Quadtree: Recursively subdivides space into four quadrants based on POI density.
- Google S2 / Uber H3: Uses spherical projections to map the Earth into cells.
Database Support
Many modern databases support spatial queries out of the box using extensions:
- PostGIS: An extension for PostgreSQL that adds support for geographic objects.
- Redis GEO: Built-in commands like GEOSEARCH for ultra-fast, in-memory proximity queries based on Geohash.
- Elasticsearch: Provides geo-point and geo-shape data types for powerful search capabilities.
Trade-offs in Geospatial Design
Concrete query: for couriers within 3 km, first use a spatial index to fetch a bounded candidate set whose cells or bounding boxes cover the circle, then exact-filter by geodesic distance, availability, tenant/permission, and a location freshness cutoff before sorting by ETA. A courier last updated five minutes ago is not made eligible by being geometrically close. Cap candidates and state whether an incomplete shard returns a partial result or an error.
Static POIs tolerate slower writes and aggressive caching. Moving couriers need frequent index updates and stale-member removal, but an in-memory index adds rebuild and failover work. Geographic partitioning reduces the working set while creating boundary queries, hot-city imbalance, and handoff work when an object crosses regions.
Worked example: sizing a covering
A user in San Francisco (latitude about 37.8) searches a 2 km radius. Geohash cells are fixed in degrees, so their width in kilometres shrinks with the cosine of latitude.
- Precision 5 (0.0439 degrees of longitude by 0.0439 of latitude): about 3.9 km wide by 4.9 km tall here. The 4 km wide circle fits inside the center cell plus its 8 neighbours: 9 cells covering about 171 square km, while the circle is only 12.6 square km, so roughly 7 percent of candidates are real hits.
- Precision 6 (about 0.98 km by 0.61 km here): the circle needs about 6 x 8 = 48 cells covering about 29 square km, so about 44 percent are hits, at the price of 48 key lookups.
- At a density of 500 places per square km, precision 5 returns about 85,000 candidates and precision 6 about 14,000, of which about 6,300 are inside 2 km. Rank by relevance and distance and return the top 20. For very dense areas, cap candidates or shrink the radius.
Technology choices
| Option | Best for | Strength | Weakness |
|---|---|---|---|
| PostGIS with a GiST index | Static POIs with rich filters and joins | Exact geography types, SQL, polygons | Write-heavy moving objects; single-node scaling limits |
| Elasticsearch or OpenSearch geo_point | Search combined with text and facets | Distance filters plus relevance scoring | Refresh lag; operational weight |
| Redis GEO | Hot, frequently updated positions | In-memory, simple commands | One key per shard; no per-member expiry |
| In-memory quadtree or grid service | Custom, very high QPS | Adapts to density, full control | You own rebuilds, replication and failover |
| H3 or S2 cell IDs in any key-value store | Global scale, sharding by cell | Uniform cell hierarchy, easy partitioning | Still needs exact filtering and coverings |
Scaling the read path
- POI data changes rarely, so a proximity service is read-heavy: keep the index in memory on stateless replicas and rebuild or update from a change stream.
- Cache results per (cell, filter) for popular areas; business details are cached separately by ID.
- Partition by region only if the dataset outgrows one machine; 200 million POIs at about 50 bytes of index entry each is about 10 GB, which still fits in memory on one large node.
How real systems do it
- Yelp has written about using Elasticsearch for location-aware search.
- Uber open-sourced H3 and indexes marketplace data by hexagonal cell.
- Tinder described geosharding its recommendation index by S2 cells so each query touches only a few shards.