Under the Hood: Write-Ahead Logging & The ARIES Protocol
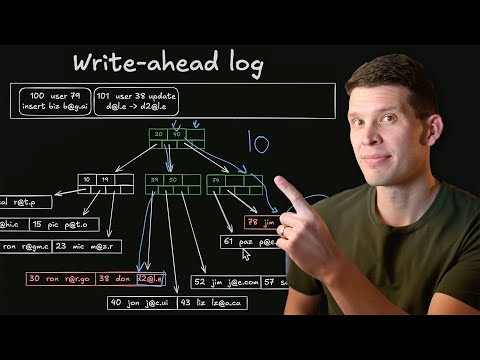
When a transaction commits, writing modified data pages to random locations on disk would require dozens of slow random I/O seeks. To achieve both ACID durability and high throughput, relational databases enforce the Write-Ahead Logging (WAL) invariant: No data page may be written to physical disk until the corresponding log entry recording the change is safely flushed to non-volatile storage.
The WAL Commit and Checkpoint Lifecycle
Under the Hood: Crash Recovery (ARIES Algorithm)
If power fails, dirty pages in memory are lost. Upon reboot, ARIES-style engines (InnoDB, SQL Server, DB2) execute the three phases of the ARIES protocol (Algorithms for Recovery and Isolation Exploiting Semantics). PostgreSQL uses a redo-only variant: it replays WAL from the last checkpoint's redo point and relies on MVCC to keep uncommitted changes invisible, so it has no undo phase or CLRs.
- 1. Analysis Phase: Scans the WAL forward from the last successful checkpoint to identify active transactions and dirty pages at the instant of failure.
- 2. Redo Phase: Rolls the database forward starting from the smallest recLSN in the dirty page table (which can be earlier than the checkpoint), reapplying all changes (even for transactions that were subsequently aborted) to restore the exact physical state before the crash.
- 3. Undo Phase: Scans backward, rolling back all transactions that were still uncommitted at the moment of the crash and writing Compensating Log Records (CLRs).
Worked example: why group commit matters
An NVMe SSD with power-loss protection completes an fsync in roughly 0.05-0.5 ms. A consumer SSD or cloud network volume may take 1-10 ms.
- With one fsync per commit at 2 ms per fsync, a single connection manages at most about 500 commits/s.
- With group commit, the WAL writer flushes all commit records waiting in the buffer with one fsync. If 50 sessions commit within the same 2 ms window, one fsync makes all 50 durable, giving about 25,000 commits/s on the same disk.
synchronous_commit = offin PostgreSQL acknowledges before the fsync. You may lose the last few hundred milliseconds of commits (about 3xwal_writer_delay) on a crash, but the database will not corrupt. It is a durability trade-off, not a consistency one.
Crash recovery timeline
Trade-offs in WAL configuration
| Setting | Lower value | Higher value |
|---|---|---|
| checkpoint_timeout / max_wal_size | Faster recovery, more I/O and full-page writes | Smoother I/O, longer recovery after a crash |
| synchronous_commit | off: faster, may lose recent commits | remote_apply: waits for a replica, slower but no data loss on failover |
| full_page_writes | off: less WAL but torn pages possible | on (default): protects against partial 8 KB writes |
How real systems use the log
- PostgreSQL: redo-only WAL. There is no undo phase, because MVCC makes aborted tuples invisible and vacuum removes them later. The same WAL feeds streaming replication and logical decoding (CDC).
- MySQL InnoDB: redo log plus separate undo logs, which is closer to ARIES. The binlog is a second, logical log used for replication, coordinated with the redo log via two-phase commit.
- Aurora and Neon: "the log is the database". Compute ships only WAL to a distributed storage layer, which materializes pages itself.
- Kafka and Raft: the same append-only log idea generalized to distributed systems.