Raw Events vs Derived Analytics
A fundamental debate in analytics architecture is whether to store raw events forever, or to pre-aggregate (derive) the data and throw the raw events away to save storage.
The Value of Raw Events
Raw event data (e.g., every single click, JSON payload, and timestamp stored in S3) is the ground truth. The primary advantage is flexibility. If a product manager asks a totally new question ("How many users clicked X, then Y, but only on iOS 14?"), you can write a Spark job to query the raw data and get the answer. If you only saved pre-aggregated daily counts, you cannot answer this question retroactively.
The Necessity of Derived Analytics
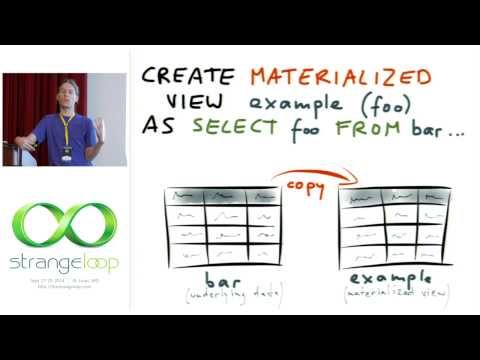
However, running complex queries over petabytes of raw data is extremely slow and expensive. Dashboards cannot wait 10 minutes for a Hadoop job to finish. Therefore, systems build ETL pipelines to continuously pre-aggregate data (derived analytics) into OLAP databases (like ClickHouse) so dashboards load instantly.
The Best of Both Worlds
Modern architectures often retain bounded raw history in object storage and serve versioned derived tables from an OLAP store. For example, if fraud rule v2 excludes two impressions that rule v1 counted, rebuild into a new aggregate version, validate it, then atomically switch the report; mutating rows in place can leave mixed definitions. Raw retention enables replay but increases privacy, deletion, schema-evolution, and storage obligations. Record event schema, transformation version, source range, and correction lineage, and define what happens when source history has expired.
Worked example: storage and query cost
| Layer | Assumption | Size | Query latency |
|---|---|---|---|
| Raw JSON events | 10 billion events per day x 500 bytes | 5 TB per day | Minutes to hours |
| Raw in Parquet | Columnar, compressed about 5 to 10 times | 0.5 to 1 TB per day; 90 days is about 45 to 90 TB | Seconds to minutes with a query engine |
| Hourly aggregates by ad, country, device | Sparse rollup | Tens of GB per day | Sub-second in an OLAP store |
| Dashboard tiles | Pre-computed top-level metrics | MB | Milliseconds |
The 1,000 to 100,000 times reduction from raw to aggregate is what makes dashboards instant, and also what makes new questions impossible once raw data is gone.
Trade-offs
| Approach | Flexibility | Cost | Risk |
|---|---|---|---|
| Aggregates only | Low | Lowest | Cannot fix bugs or answer new questions |
| Raw only, query on demand | Highest | High compute per query | Slow dashboards, unpredictable bills |
| Raw with bounded retention plus versioned aggregates | High | Moderate | Needs lineage and a deletion process |
Lambda vs Kappa
Lambda runs a batch layer over raw storage for correctness and a speed layer for freshness, then merges them; the cost is two codebases computing the same logic. Kappa, popularised by Jay Kreps at LinkedIn, keeps a replayable log and reprocesses history by running a new version of the streaming job from the beginning of the retained log, then switching readers. Kappa needs long log retention or tiered storage, which Kafka and Pulsar now offer.
Privacy obligations
Under GDPR-style deletion requests, raw events containing a user ID must be deleted or anonymised within the required period, including in backups and derived tables that are not fully aggregated. Common patterns are partitioning raw data by date so whole partitions age out, pseudonymising user IDs with a per-user key that can be destroyed (crypto-shredding), and aggregating to levels where individuals cannot be identified.