Under the Hood: Designing Schemas for Inevitable Change
Software requirements continuously evolve, but altering production database schemas with millions of records introduces lock contention, table rewrites, and migration downtime. Extensible Data Modeling balances strict relational integrity against the agility required to accommodate dynamic, polymorphic, or rapidly mutating business attributes.
Extensibility Patterns Compared
Core Production Strategies
1. Hybrid Relational + Semi-Structured (JSONB)
Modern production architectures retain relational columns for core, indexed, and audited identifiers (id, account_id, status, created_at) while storing dynamic or third-party metadata in binary JSON (JSONB in PostgreSQL; MySQL 8 has a binary JSON type indexed through generated columns or multi-valued indexes). In PostgreSQL, Generalized Inverted Indexes (GIN) let containment and key-existence queries on JSONB use an index instead of a full table scan.
2. The EAV Anti-Pattern & Pitfalls
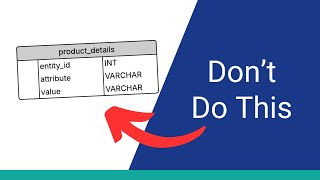
Entity-Attribute-Value (EAV) models store attributes across three generic columns: EntityID, AttributeKey, Value. While allowing infinite runtime attribute creation, querying multiple attributes requires repeated self-joins, forfeits native foreign-key constraints, and degrades database query planners. JSONB columns or dedicated document stores are usually a better choice; keep EAV for rare cases such as extremely sparse, user-defined attributes where JSON is unavailable.
3. The Expand-Migrate-Contract Pattern
Never rename or remove columns in a single deployment. Step 1 (Expand): Add the new nullable column alongside the old. Step 2: Update application code to dual-write to both columns while still reading from the old one. Step 3 (Migrate): Backfill historical rows asynchronously in batches, verify the backfill, then switch reads to the new column. Step 4 (Contract): Remove the old column once all dependent code is retired.
Worked example: renaming a column with expand/contract
Suppose the links table has a column url that should become destination_url, with 1.8 billion rows and continuous traffic. A single RENAME would break every running instance that still uses the old name. Instead:
- Expand: add
destination_urlas a nullable column. In PostgreSQL 11 and later, adding a nullable column (or one with a constant default) is a fast metadata-only change. - Dual-write: deploy code that writes both columns but still reads
url. New rows are now complete in both. - Backfill: copy old rows in batches, for example 10,000 rows per transaction by primary key range. At about 2,000 batches per minute that is roughly 20 million rows per minute, so 1.8 billion rows takes around 90 minutes, throttled to keep replication lag low.
- Switch reads: once the backfill is verified (count of rows where the columns differ is zero), deploy code that reads
destination_url. - Contract: stop writing
url, wait until no running version uses it, then drop it.
Every step is independently deployable and reversible until the final drop. Tools such as pgroll, gh-ost (MySQL) and pt-online-schema-change automate parts of this.
Choosing a flexibility pattern
| Pattern | Good for | Costs |
|---|---|---|
| Typed columns | Data that is always present, filtered, joined or constrained | Schema migration for every change |
| JSON or JSONB column | Per-tenant custom fields, third-party payloads, sparse product attributes | Weaker typing; indexes needed per access path; validation in application or check constraints |
| Entity-Attribute-Value table | Extremely sparse attributes defined at runtime by users, when JSON is unavailable | Self-joins per attribute, all values stored as text, no per-attribute constraints |
| Single table with type discriminator | A few subtypes sharing most fields | Many nullable columns as subtypes diverge |
| Table per subtype | Subtypes with distinct required fields and constraints | Joins or unions to query across all types |
Indexing flexible data in PostgreSQL
- A GIN index on a JSONB column supports containment queries such as
attributes @> '{"color": "red"}'. - For one frequently filtered key, an expression index on
(attributes ->> 'color')or a generated column with a B-tree index is usually smaller and faster. - MySQL stores JSON in a binary format but has no GIN; index JSON values through generated columns or multi-valued indexes.
Failure modes
- Backfills that run too fast cause replica lag and lock contention; throttle and monitor.
- Dropping the old column while an old deploy or a batch job still reads it causes errors; check query logs first.
- JSON attributes that become business-critical should be promoted to real columns with the same expand/contract steps.