
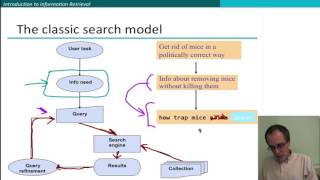
Under the Hood: Search Engine Architecture
Traditional relational databases optimize for exact-match point lookups and transactional ACID guarantees using B-Trees. An Information Retrieval (IR) system (such as Apache Lucene, Elasticsearch, and Google Search) is engineered for full-text search, unstructured natural language understanding, fuzzy matching, and multi-factor relevance ranking across billions of documents.
Dual-Plane IR Pipeline: Indexing vs Query Serving
Under the Hood: The Indexing Anatomy
- Character Filters: Strip HTML markup, decode entities (e.g.
&->&), and map custom regex patterns. - Tokenizer: Breaks continuous text streams into discrete linguistic tokens based on word boundaries, punctuation, and Unicode script rules.
- Token Filters: Lowercases tokens, removes stop words (optional), expands synonyms, and applies stemming algorithms (reducing "running", "runs", "ran" to the common root "run").
Worked example: a 200 ms search latency budget
Suppose an e-commerce site indexes 200 million products and promises p99 search latency of 200 ms at the edge. A realistic budget looks like this:
| Stage | Budget | What happens |
|---|---|---|
| Network and TLS to the edge | 40 ms | Client to nearest region |
| Query parsing and understanding | 10 ms | Analyzer, spell check, entity tagging |
| Candidate retrieval | 40 ms | Scatter to shards, postings intersection, BM25, local top 1,000 |
| Re-ranking | 50 ms | ML model scores roughly 1,000 candidates using hundreds of features |
| Fetch and highlight | 20 ms | Load stored fields for the final 20 hits |
| Headroom | 40 ms | GC pauses, retries, slow shards |
The key design insight is the funnel: cheap scoring on millions of postings, expensive scoring on only a thousand candidates, and full document fetch for only the final page.
Search engine vs relational database
| Concern | Relational DB | Search engine such as Lucene |
|---|---|---|
| Core structure | B-tree on keys | Inverted index of term to sorted doc IDs |
| Answer type | Exact set of matching rows | Ranked list, usually top K |
| Writes | In-place, transactional | Buffered into immutable segments, visible after refresh |
| Consistency | Read-your-writes | Near-real-time, typically about 1 s behind |
| Best at | Joins, constraints, updates | Full text, fuzzy match, facets, relevance |
Failure modes to plan for
- Analyzer drift: changing a tokenizer or synonym list without reindexing makes old and new documents disagree about what a term is.
- Hot queries: a small set of head queries dominates traffic; a result cache in front of the engine often absorbs a large share of load.
- Slow shard tail: a query waits for the slowest of N shards, so p99 per shard matters more than the average.
Real systems follow this shape: Elasticsearch and OpenSearch wrap Lucene segments with a distributed coordinator; Google described serving its index from memory across thousands of machines with a multi-level tree of root, parent and leaf servers.