
The Core Architectural Dilemma: Fan-out on Write vs. Fan-out on Read
When designing news feeds (Twitter/X, Facebook, LinkedIn), the fundamental architectural choice is how and when to assemble the timeline for each user.
Fan-out on Write (Push Model)
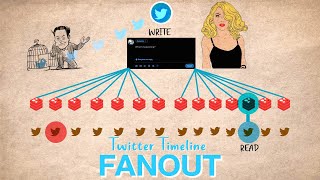
When a user posts a status update, a background worker looks up all followers and immediately injects the post ID into each follower's pre-computed in-memory feed cache (e.g., Redis List or sorted set):
- Pros: Generating the timeline when a user opens the app is virtually instant (O(1) read from Redis cache).
- Cons: Severe write amplification. If a celebrity with 80 million followers posts, the system must perform 80 million cache writes, overloading background queues.
Fan-out on Read (Pull Model)
Posts are only written to the author's own timeline. When a follower opens their home feed, the system queries the latest posts of everyone they follow and merges them dynamically:
- Pros: Writes are constant time O(1). No write amplification for celebrities.
- Cons: Read latency is high; fetching and merging posts from hundreds of followed accounts on every feed refresh causes database and CPU bottlenecks.
The Production Hybrid Solution
Modern social networks implement a hybrid fan-out model:
- Standard users (e.g., < 25,000 followers) use Fan-out on Write, pre-populating followers' Redis feeds.
- Celebrity accounts (e.g., > 25,000 followers) bypass fan-out on write. Instead, when a follower views their feed, the system fetches the celebrity's recent posts and merges them into the cached timeline in real time.
Worked example: write amplification
- 200 million daily active users, 40 million posts per day, and an average of 300 followers per author gives 12 billion timeline inserts per day, about 140,000 per second on average and perhaps 500,000 at peak. That is manageable across a Redis fleet.
- A single account with 80 million followers would add 80 million inserts for one post, taking minutes even at 500,000 per second. That is why the hybrid threshold exists.
- Timeline memory: if each of 200 million users keeps 800 IDs at 8 B, that is about 1.3 TB of raw IDs, perhaps 3 to 4 TB with Redis overhead. Caching only active users, and capping lists (Twitter publicly described keeping about 800 entries per home timeline), keeps this bounded.
Strategy comparison
| Strategy | Post cost | Feed-read cost | Freshness | Weak spot |
|---|---|---|---|---|
| Push (fan-out on write) | One insert per follower | One range read plus hydration | Seconds of fan-out lag | Celebrities, deletes (must also be fanned out) |
| Pull (fan-out on read) | One insert | Read N followees and k-way merge | Immediate | Users who follow many accounts; expensive at read time |
| Hybrid | Push for ordinary authors, skip for big ones | Cached timeline plus a merge of a few celebrity lists | Good | More complex; the threshold needs tuning |
| Ranked feed (Facebook, Instagram) | Candidates indexed per author | Gather thousands of candidates, then ML ranking | Good | Ranking latency and cost |
Read path for the hybrid
Meta's ranked News Feed gathers candidates from followed sources at read time and scores them with ML models. That is closer to "pull plus ranking" than to a pure pushed list, because the ordering depends on the viewer and the moment. Twitter's classic home timeline was mostly push into Redis, with celebrity tweets merged at read time.