The Core Thesis of Log-Structured Systems
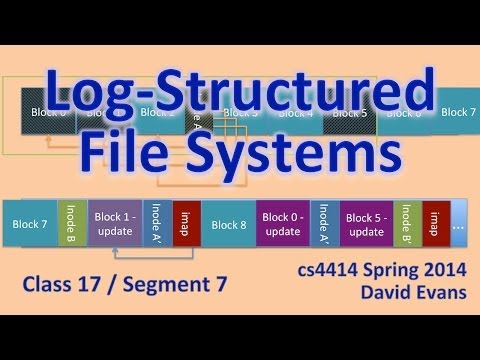
In 1991, Mendel Rosenblum and John Ousterhout published the seminal paper on Log-Structured File Systems (LFS). Their core thesis remains the foundation of high-performance database engineering today: disks handle large sequential writes far more efficiently than small random ones. By transforming all updates, deletes, and insertions into a single append-only sequential log, write performance approaches theoretical hardware limits.
Log-Structured Write Flow
The Fundamental Challenge: The Cleaner & Space Reclaim
Because every update appends a new record and every delete appends a tombstone, the log grows without bound until it is cleaned. A log-structured engine requires a background Cleaner / Compaction Engine:
- The cleaner selects cold or fragmented log segments.
- It reads the segment into RAM and identifies the latest valid version of each key by consulting an index.
- It discards overwritten values and tombstones.
- It writes the active surviving records into a new, contiguous log segment and unlinks the old files.
Worked example: the cost of cleaning
The LFS paper models cleaning with segment utilization u, the fraction of a segment that is still live when the cleaner picks it. To free one segment's worth of space, the cleaner reads the whole segment (1), writes back the live part (u), and gains room for 1 - u of new data. The paper's write cost, total bytes moved per byte of new data, is 2 / (1 - u).
| Utilization of cleaned segments | Write cost | Interpretation |
|---|---|---|
| 0.2 | 2.5 | Cheap: mostly garbage |
| 0.5 | 4 | Moderate |
| 0.8 | 10 | Expensive: 10 bytes of I/O per byte written |
| 0.9 | 20 | Near-stall territory |
This is why cleaning policy matters. LFS found that a cost-benefit policy (prefer segments with lots of free space and old, stable data) beats greedy "emptiest segment first", because cold data stays put and hot data dies quickly in its own segments.
In-place versus log-structured
| Property | Update in place | Log-structured |
|---|---|---|
| Write pattern | Random | Sequential appends |
| Crash recovery | WAL replay plus torn-page protection | Replay from last checkpoint in the log |
| Space overhead | Low | Dead versions until cleaned |
| Background work | Checkpointing | Cleaning or compaction, often the bottleneck |
| Read locality | Stable, by key or page | By write time unless compacted |
Where the idea shows up
- SSD firmware: the flash translation layer is itself log-structured, with its own garbage collector.
- Kafka: append-only segments; retention deletes whole old segments, and log compaction keeps only the latest record per key.
- LSM-trees (RocksDB, Cassandra, Bigtable): the log becomes sorted runs, and cleaning becomes compaction.