Under the Hood: Deployment Boundaries vs. Domain Boundaries
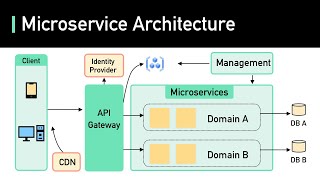
The debate between monolithic and microservice architectures is fundamentally an organizational and operational trade-off, not merely a code structure decision. A Monolith packages all business logic into a single deployable artifact accessing a unified database. A Microservices Architecture decomposes the domain into independently deployable services communicating over the network, each encapsulating its own private datastore.
Architectural Topologies Compared
Core Production Invariants
1. The Distributed Network Tax
In a monolith, calling from the order module to the payment module is an in-process function call costing nanoseconds to microseconds. In microservices, that call crosses TCP network boundaries, introducing serialization overhead (JSON/Protobuf), connection management, service discovery (DNS lookups are normally cached, not per call), TLS encryption, and non-deterministic packet latency. Every inter-service hop increases the p99 tail latency budget.
2. Data Consistency: ACID vs. Eventual Consistency (Sagas)
Monoliths enforce consistency through ACID database transactions with atomic rollbacks. When services split databases, cross-service atomic transactions require a distributed commit protocol such as Two-Phase Commit, which is rarely used between services because it blocks when the coordinator fails. The common alternative is a Saga (orchestrated or choreographed) with compensating transactions, which provides eventual consistency rather than atomicity: intermediate states are visible and compensations can fail.
3. A Common Default: Modular Monolith First
Unless multiple independent engineering teams are stepping on each other's release cadence, start with a Modular Monolith. Enforce strict package boundaries with clean interfaces in a single codebase. Only carve out a microservice when a specific sub-domain requires distinct hardware scaling (e.g., GPU video processing) or independent compliance isolation.
Worked example: the cost of one extra hop
Consider a checkout request that, in a monolith, calls the order module, inventory module and payment module in process. Each call costs microseconds. Split into services, each call becomes a network round trip. Inside one data centre a small RPC typically costs around 0.5 to 2 ms including serialization, so three sequential calls add roughly 2 to 6 ms at the median. That sounds small, but the tail compounds.
If each service independently meets its latency target 99% of the time, a request that must call all three sequentially meets it only about 0.99 x 0.99 x 0.99 = 97% of the time. Availability multiplies the same way: three dependencies at 99.9% each give at most about 99.7% for the combined path, before counting the caller's own failures. This is why microservice systems need timeouts, retries with budgets, circuit breakers and good tracing from day one.
Data consistency changes too. In the monolith, "create order and reserve stock" is one database transaction. Across services it becomes a saga: order service writes a pending order and publishes an event, inventory reserves stock and publishes a result, and a failure triggers a compensating "cancel order". The user can briefly see a pending order that later disappears; the design must decide whether that is acceptable.
Trade-off table
| Concern | Modular monolith | Microservices |
|---|---|---|
| Deploying one change | Redeploy the whole application | Deploy one service independently |
| Cross-module call | In-process function call | Network call with latency, partial failure and versioning |
| Transactions | Single database ACID transaction | Sagas, outbox pattern, eventual consistency |
| Scaling | Scale the whole app together | Scale hot services separately, for example GPU transcoding |
| Fault isolation | A memory leak or bad deploy affects everything | Failures can be contained if timeouts and bulkheads exist |
| Operational load | One pipeline, one set of dashboards | Per-service pipelines, tracing, service discovery, on-call |
| Refactoring boundaries | Move code between packages | Migrate data and APIs between services |
Signals that a split is justified
- Several teams block each other on a shared release train, and the conflicting code has a clear domain boundary.
- One component has very different resource needs or scaling patterns, such as video transcoding or ML inference.
- A component needs a separate security or compliance boundary, such as card data handling under PCI DSS.
- A component's failure should not take down the rest, and you are prepared to make callers tolerate its absence.
How real systems do it
Shopify runs one of the largest Ruby on Rails applications as a modular monolith, enforcing component boundaries with tooling rather than splitting into services. Amazon and Netflix moved to services to let hundreds of teams deploy independently. Amazon Prime Video published a case in 2023 where consolidating a distributed monitoring pipeline into a single process cut its infrastructure cost by about 90%, a reminder that the right answer depends on the workload.