
A companion from-scratch implementation is available in the builds catalog: Tiny Search Engine (Inverted Index, Compression & BM25).
Under the Hood: The Inverted Index Data Structure
Traditional relational databases organize data around documents or rows (DocID → Text content). Evaluating a full-text search query like WHERE content LIKE '%consensus%' forces a full table scan across millions of rows (O(N) execution time).
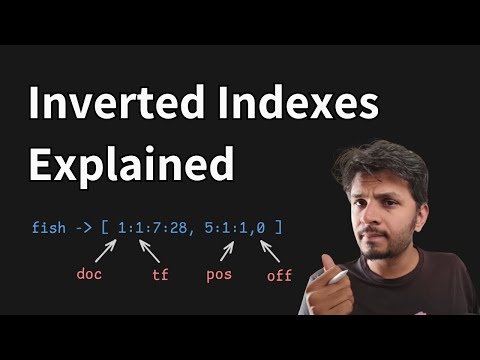
An Inverted Index reverses this relationship: every distinct vocabulary term points to a strictly sorted list of Document IDs where it appears (Term → [DocIDs]). This sorted sequence is called a Postings List.
Forward Index vs Inverted Index
The Document Ingestion Pipeline
- Tokenization & Normalization: Strips punctuation, folds Unicode cases, and splits raw continuous character streams into discrete linguistic tokens.
- Stop-Word Elimination: Filters out ubiquitous, low-information entropy words (such as "the", "is", "at", "which") that appear in nearly all documents.
- Stemming & Lemmatization: Reduces word inflections to a shared root. Algorithmic stemmers (Porter or Snowball) strip morphological suffixes (reducing "searching", "searched", "searches" to
search), ensuring that variant forms match the user's intent.
Postings Lists & The Two-Pointer Intersection Invariant
The single most important invariant of an inverted index is that document IDs within each postings list must be strictly sorted in ascending order ([1, 4, 12, 99]).
When evaluating multi-term conjunction queries (e.g. distributed AND consensus), the engine does not perform an O(N × M) nested loop. Instead, it advances two cursors concurrently across the sorted lists in linear O(N + M) time:
- If
DocID_A == DocID_B, record a match and increment both pointers. - If
DocID_A < DocID_B, advance pointer A forward. - If
DocID_A > DocID_B, advance pointer B forward.
Query Optimization: When intersecting three or more terms, the engine always sorts the postings lists by length in ascending order (rarest terms first). Intersecting the smallest list first dramatically shrinks intermediate candidate sets.
Postings List Compression: Delta Gaps & Variable Byte
At web scale, storing raw 32-bit integers for billions of document IDs would require petabytes of storage and swamp memory bandwidth. Search engines use a two-step compression pipeline:
- Delta (Gap) Encoding: Instead of storing absolute IDs (
[1000, 1004, 1008, 1020]), the engine stores differences between consecutive IDs ([1000, 4, 4, 12]). Because postings lists are sorted, all delta gaps are small positive integers. - Variable-Byte (VByte) & Frame of Reference (FoR): Standard 32-bit integers require 4 bytes. VByte encodes numbers into 7 bits per byte with a 1-bit continuation flag. Values < 128 consume only 1 byte, yielding an immediate 75% storage reduction. Lucene packages blocks of 128 integer deltas using Frame of Reference (FoR) bit-packing.
Skip Lists and Champion Lists
- Skip Pointers: When intersecting a short postings list with a multi-million-item postings list, scanning every item is wasteful. Skip pointers allow the engine to leap forward past entire blocks of non-matching IDs in sublinear time.
- Champion Lists: For each term, the engine precomputes a short list of the top-
rdocuments with the highest weight for that term. Queries first evaluate only these per-term champion lists and fall back to the full postings when too few candidates are found. - Tiered Indexes (a different technique): The whole corpus is partitioned by a global static quality score (PageRank, sales velocity). Queries run against the high-quality Tier 1 first and cascade to lower tiers only if Tier 1 returns too few matches.