Case: How Discord Stores Trillions of Messages
A message store has to serve both a crowded channel with thousands of active chatters and a quiet direct message conversation whose latest messages are months old. Discord's database history shows why those two reads stress different parts of the same system.
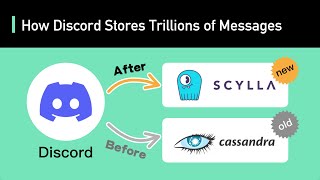
Discord started with MongoDB, migrated to Cassandra to handle billions of messages, and more recently migrated to ScyllaDB to handle trillions. The evolution is a masterclass in understanding database architectures.
The Migration to Cassandra
Starting around late 2015, after reaching about 100 million stored messages, Discord moved from MongoDB to Cassandra (the move was described in a January 2017 blog post). They needed a database that provided linear scalability, high availability, and fast writes. Cassandra, a wide-column NoSQL store, fit the bill perfectly because of its LSM-tree architecture, which makes writes incredibly fast.
Discord's published Cassandra design bounded partitions with a composite partition key such as (channel_id, bucket) and ordered messages by a timestamp-bearing message_id. Replication placed each partition on multiple nodes; bucketing limited partition size but did not spread one currently hot bucket across many write owners.
Partition Size and Hot Buckets
Time buckets keep a channel's lifetime history from becoming one unbounded partition and let old buckets age independently. They do not solve every hot-key problem: all writes for one channel's current bucket still target that partition's replica set. A sudden viral channel can therefore overload its current owners until the workload is further sharded, buffered, or moved.
Read Performance and Garbage Collection
Cassandra is written in Java. As Discord scaled to trillions of messages, the Java Garbage Collector (GC) became a massive bottleneck. When GC paused the application to clean up memory, latency spiked across the cluster, causing cascading timeouts.
Furthermore, reading old messages required waking up disks and reading multiple SSTables (immutable data files on disk). To mitigate this, Discord built Rust-based data services in front of the database that route requests by channel and collapse multiple simultaneous queries for the same data into a single database query (request coalescing); they are a traffic-shaping layer, not a cache.
The Move to ScyllaDB
Ultimately, Discord migrated from Cassandra to ScyllaDB. ScyllaDB's C++ shard-per-core architecture avoids JVM garbage-collection pauses and offers substantial CQL compatibility, but predictable latency still depends on compaction, disks, caching, repair, and data modeling. Discord also changed service and query behavior during the migration; compatibility did not make the systems operationally identical.
The numbers Discord published
| Item | Value |
|---|---|
| 2017 schema | Partition key (channel_id, bucket), clustering by message_id (Snowflake, time ordered); buckets of about 10 days |
| Cassandra cluster before migration | 177 nodes |
| ScyllaDB cluster after migration | 72 nodes, each with far more disk (about 9 TB vs 4 TB) |
| p99 historical message fetch | About 40-125 ms on Cassandra vs about 15 ms on ScyllaDB |
| p99 message insert | About 5-70 ms on Cassandra vs a steady 5 ms on ScyllaDB |
| Migration speed | A Rust migrator moved data at up to about 3.2 million messages per second, finishing in about 9 days |
Worked example: why buckets bound partitions
A busy channel receives 200 messages per minute of about 1 KB. Unbucketed, one year is 105 million messages, about 105 GB in a single Cassandra partition, which is far beyond the range where compaction and repair behave well. With 10-day buckets, each partition is about 2.9 million messages, around 3 GB for this extreme channel, and small for nearly every other channel. Reading the latest messages touches only the newest bucket (and occasionally the previous one).
Request coalescing in the data services
Requests are routed by channel id (consistent hashing) so all requests for one channel reach the same data service instance, which can then merge identical in-flight queries. When a huge server announces something and 100,000 clients open the channel, the database sees a handful of queries instead of 100,000.
Lessons that transfer
- Model partitions for bounded size and for the dominant read ("latest N").
- Put a thin, stateless-looking but routing-aware service in front of the database to absorb thundering herds.
- Migrations of this size need a purpose-built, restartable, checkpointed copier and a validation pass comparing reads from both clusters.