Under the Hood: Key-Value Semantics on Relational Engines
Before introducing dedicated caching or NoSQL infrastructure (like Redis or DynamoDB), modern relational engines like PostgreSQL can reliably serve as high-throughput key-value stores using optimized schema designs, atomic compare-and-swap mutations, and partial indexing.
Schema Design for an ACID Key-Value Table
-- Production-Grade Key-Value Table in PostgreSQL
CREATE TABLE kv_store (
    key VARCHAR(255) PRIMARY KEY,
    value JSONB NOT NULL,
    version BIGINT NOT NULL DEFAULT 1,
    created_at TIMESTAMPTZ NOT NULL DEFAULT NOW(),
    updated_at TIMESTAMPTZ NOT NULL DEFAULT NOW(),
    expires_at TIMESTAMPTZ
);

-- Partial index for active key lookups and expiration sweeps
CREATE INDEX idx_kv_expires ON kv_store(expires_at)
WHERE expires_at IS NOT NULL;
Atomic Mutations: Compare-and-Swap (CAS)
To avoid lost updates without holding a lock across a read-modify-write round trip, execute conditional updates directly in SQL (the UPDATE itself still takes a short row-level lock until its transaction ends):
-- Optimistic Concurrency Control: Put-If-Version
UPDATE kv_store
SET value = '{"config": "v2"}'::jsonb,
    version = version + 1,
    updated_at = NOW()
WHERE key = 'feature_flags' AND version = 4;
-- If 0 rows updated, client knows another thread won the race!
Background Expiration Sweeper
Because expired rows consume disk space and memory buffers, a background reaper periodically purges expired keys in bounded batches using the partial index:
-- Bounded batches keep each transaction short (limits WAL bursts, replica lag and vacuum backlog)
DELETE FROM kv_store
WHERE key IN (
    SELECT key FROM kv_store
    WHERE expires_at < NOW()
    LIMIT 1000
);
Worked example: sizing a Postgres-backed config and session store
Suppose a service keeps 20 million session keys. Each value is about 400 bytes of JSONB, and the load is 5,000 reads/s and 500 writes/s at peak.
- Row size: about 24 bytes of tuple header, a key of about 40 bytes, a value of about 400 bytes, and three timestamps plus a version (about 32 bytes), so roughly 500 bytes. At 8 KB per page with fillfactor 90, that is about 14 rows per page. 20M rows is about 1.4M pages, or around 11 GB of heap.
- Primary key index: a B-tree on the key is 3 to 4 levels deep. The upper levels stay cached, so a
getis typically one or two buffer hits. With enough RAM, a point lookup is well under 1 ms on the server. - Writes: 500 updates/s produce 500 dead tuples/s, or about 43M per day, which is more than the live row count. Autovacuum must be tuned per table (for example
autovacuum_vacuum_scale_factor = 0.01). A lower fillfactor enables HOT updates, which avoid index churn when indexed columns do not change.
Upsert and TTL-aware read
INSERT INTO kv_store(key, value, expires_at) VALUES (?, ?, now() + interval '30 minutes') ON CONFLICT (key) DO UPDATE SET value = EXCLUDED.value, version = kv_store.version + 1, updated_at = now(), expires_at = EXCLUDED.expires_at;
SELECT value, version FROM kv_store WHERE key = ? AND (expires_at IS NULL OR expires_at > now());
Design choices
| Choice | Benefit | Cost |
|---|---|---|
| Regular (logged) table | Crash-safe, replicated to standbys | WAL and fsync on every commit |
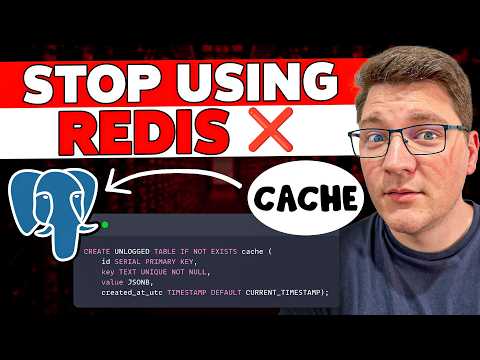
| UNLOGGED table | Several times faster writes, good for caches | Truncated after a crash; not replicated to physical standbys |
| Hash-partition by key | Smaller indexes, parallel vacuum | More objects to manage |
| Range-partition by expires_at | Expiry becomes a cheap DROP of an old partition instead of DELETE | Updates that change the TTL move rows between partitions |
Failure modes
- Lost updates: a blind
UPDATE ... SET valuefrom two clients silently loses one write. Use the version predicate orSELECT ... FOR UPDATE. - Connection exhaustion: Postgres uses one process per connection. Thousands of app instances need a pooler such as PgBouncer.
- Sweeper lag: if expiry deletes fall behind, the table grows without bound. Monitor dead-tuple counts and the age of the oldest expired row.
Who does this: Uber's Schemaless and FriendFeed's early design stored opaque JSON blobs in MySQL keyed by ID. Rails 8's Solid Cache keeps its cache in a SQL database. Many teams run feature flags and idempotency keys in Postgres tables before they ever need Redis.