Concrete scenario
Two replicas cannot communicate, and clients can still reach each side.
Mechanics
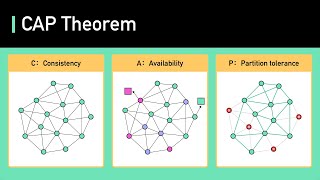
CAP asks what a replicated service does during a partition: preserve a single-copy consistency guarantee by rejecting some operations, or return a non-error response from every non-failing node and permit divergent results. Partition tolerance means the specification accounts for lost or delayed messages, not that every operation continues. PACELC additionally highlights latency-versus-consistency choices when communication is healthy.
Failure mode
Calling an entire database CP or AP hides operation, topology, and configuration. Cassandra and Dynamo-style services expose tunable behavior; MongoDB and Redis behavior depends on write concern, read routing, failover, and which partition the client reaches.
Trade-off
The product chooses behavior per operation: a payment ledger may reject uncertain writes, while a feed can serve stale data. Systems without independent replicas do not face the same distributed partition choice, though they have other availability risks.
Worked example: one product, two choices
An e-commerce site runs in two regions with a replicated database. The transatlantic link drops for 3 minutes.
- Shopping cart (choose A): both regions keep accepting "add item". When the link returns, merge the carts as a union, the way Amazon's Dynamo did for carts. A deleted item might reappear, which is an acceptable annoyance.
- Inventory decrement for the last unit (choose C): only the region that owns the item's primary can decrement. Users in the other region get "try again shortly" for 3 minutes. Overselling a limited edition is worse than a short error.
- Product descriptions (choose A, stale reads allowed): each region serves its local copy. Nobody cares about a 3-minute-old typo fix.
On a normal day (the "else" branch of PACELC), linearizable inventory reads cost a cross-region round trip of about 70 to 90 ms. Local reads cost about 1 ms but may be up to about a second stale. Most systems pick latency for browsing and consistency only at checkout.
PACELC classification (default configurations)
| System | During partition (P) | Else (E) | Notes |
|---|---|---|---|
| DynamoDB, Cassandra, Riak | PA | EL | Tunable per request: QUORUM or strongly consistent reads shift towards C |
| Spanner, CockroachDB, etcd | PC | EC | Majority required. Latency paid on every write |
| MongoDB (majority write concern) | PC | EC or EL | Reads from secondaries are EL |
| PNUTS (Yahoo) | PC | EL | The per-record master example from Abadi's paper |
Common interview traps
- Claiming "we are CA because we run in a single datacentre". A rack switch failure is still a partition.
- Forgetting that a CP system stays available on the majority side. Only the minority side rejects requests.
- Mixing up CAP with ACID isolation levels. CAP says nothing about multi-key transactions.
What partitions look like in practice
Real partitions are rarely a clean split. More often a single node loses connectivity to the leader but not to clients, a switch drops a fraction of packets, or one direction of a link fails. A CP system like etcd handles this by having the isolated node reject writes once it cannot reach a majority. An AP system like Cassandra keeps serving, stores hints for unreachable replicas, and relies on read repair and anti-entropy repair to converge afterwards.