Under the Hood: Sticky Routing & Cache Locality
Traditional load balancing sends requests to any available server. For stateful caching tiers (e.g., in-process memory, local SSD caches), routing requests randomly forces every node to cache the whole working set, cutting effective cache capacity by about N times and lowering hit rates. Simple modulo hashing (hash(key) % N) achieves sticky routing, but adding or removing a single server shifts nearly 100% of keys, triggering a devastating cache stampede. Consistent Hashing solves this by ensuring that scaling moves only K/N keys.
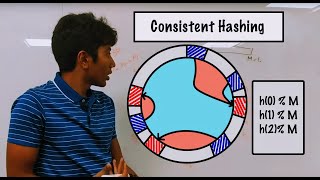
Consistent Hashing with Virtual Nodes
Under the Hood: Bounded-Load Consistent Hashing
Standard consistent hashing can still create hot spots if a single partition key goes viral (e.g., a breaking news post). Google Research introduced Consistent Hashing with Bounded Loads (used in Vimeo and HAProxy):
- Each server is assigned a maximum capacity threshold: 1 + ε times the average cluster load (e.g., 1.25×).
- When a request hashes to server S, the load balancer checks if S is currently at or above its load ceiling.
- If overloaded, the load balancer skips S and walks clockwise along the ring to the next available virtual node, strictly capping load while preserving maximum possible cache affinity.
Worked example: how many keys move
A cache tier has 10 servers and 100 million keys.
- Modulo hashing (hash mod N): going from 10 to 11 servers, a key stays put only if hash mod 10 equals hash mod 11, which happens for about 1 in 11 keys. So roughly 91 million keys (about 91%) move, and the cache hit rate collapses while the database absorbs the misses.
- Consistent hashing: the new server takes over about 1/11 of the ring, so roughly 9 million keys (about 9%) move, all onto the new server. The other 10 servers keep their contents.
Virtual nodes: with a single point per server on the ring, the largest arc can easily be 2 to 3 times the average. With about 100 to 200 virtual nodes per server, the load spread typically tightens to within roughly 10% of the mean. The cost is a larger ring lookup table, still tiny (2,000 entries for 10 servers), searched by binary search.
Bounded loads: with a capacity factor of 1.25, no server may hold more than 1.25 times the average current load. If a key's home server is full, the request walks clockwise to the next server with spare capacity. Vimeo reported that this change in HAProxy made bandwidth across its cache servers far more even, at the cost of a small reduction in cache hit rate.
Variants and trade-offs
| Scheme | Keys moved on change | Balance | Notes |
|---|---|---|---|
| Modulo hashing | Almost all | Good | Only for fixed N |
| Ring with virtual nodes (Karger et al. 1997) | About 1/N | Good with enough vnodes | Used by Cassandra, DynamoDB lineage, Memcached clients |
| Rendezvous (highest random weight) | About 1/N | Good without vnodes | O(N) per lookup; simple and memory-light |
| Jump consistent hash (Google 2014) | About 1/N | Very even | Servers must be numbered 0 to N-1; removing from the middle is hard |
| Maglev hashing | Small | Very even | Lookup table for fast packet steering in L4 balancers |
| Bounded-load consistent hashing (Mirrokni, Thorup, Zadimoghaddam 2016) | Slightly more than 1/N | Capped at (1 + epsilon) times average | HAProxy, Vimeo, Envoy supports a similar option |
Failure modes
- Clients with different server lists: if two clients see different membership, they send the same key to different servers and caches diverge.
- Cascading overload: when a server dies, its whole arc moves to the next server clockwise unless virtual nodes spread it across many.
- Cold server after join: the new server starts with an empty cache, so the database briefly sees about 1/N extra misses.