The Two-Dimensional Spatial Indexing Problem
Two independent scalar B-tree indexes do not directly provide a nearest-neighbor search. An unindexed latitude/longitude bounding-box query may scan many rows, while databases with GiST, R-tree, geography, or other spatial indexes can serve this workload efficiently. The design choice is between those native spatial capabilities and an application-managed cell index—not SQL versus indexing.
Spatial Indexing Strategies
Geohash & Peano Space-Filling Curves
Geohashing recursively subdivides the globe into a grid and maps 2D coordinates into a 1D alphanumeric string using a Z-order space-filling curve. Locations sharing the same prefix are geographically proximate:
- Precision 5: ~4.9 km × 4.9 km cell (city district scale)
- Precision 6: ~1.2 km × 0.6 km cell (neighborhood scale)
- Precision 7: ~152 m × 152 m cell (street block scale)
To find places within 1 kilometer, cover the search circle with every cell it intersects at the chosen precision, query those cells, and apply an exact spherical-distance filter. Center plus eight neighbors is a useful small-grid example, not a universal guarantee: geohash cell dimensions vary with precision and latitude, and a radius can span more cells.
Dynamic Drivers vs. Static Places
For static places (restaurants, ATMs in Yelp/Google Places), data is indexed into Geohash or QuadTree shards and heavily cached. For dynamic moving objects (Uber/Lyft drivers updating coordinates every 4 seconds), coordinates are written to an in-memory spatial index (like Redis Geospatial commands backed by sorted sets) to prevent database write saturation.
Worked example: 1 km search with geohash
- The user is at latitude 40.7580, longitude -73.9855 (Times Square). At precision 6 a cell is about 1.2 km x 0.61 km at the equator; cells get narrower east to west as latitude increases.
- A 1 km radius spans about two cells north to south and several east to west, so the covering set is roughly 9 to 15 cells, not always exactly 9.
- Each cell lookup is a range scan on a geohash-prefixed key, in a Redis sorted set or a DB index. With Manhattan densities of 1,000 to 3,000 places per cell, you gather perhaps 20,000 candidates.
- Exact haversine filtering of 20,000 points takes about 1 ms of CPU. Then sort by distance or rank, and return the top 20.
- For sparse areas, widen progressively: precision 6, then 5, then 4, until at least K results are found.
Index options
| Index | Cell shape | Adapts to density | Strength | Weakness |
|---|---|---|---|---|
| Geohash | Rectangles on a Z-order curve | No | Plain string prefixes; works in any KV store or Redis GEO | Edge discontinuities; cell shape varies with latitude |
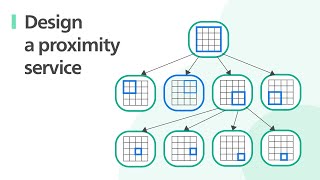
| Quadtree | Squares split recursively | Yes (split when a leaf exceeds N points, for example 100) | Balanced load in dense and sparse areas | Usually an in-memory structure; rebuilding it is costly for moving points |
| S2 (Google) | Spherical quadrilaterals on a Hilbert curve | Multi-level coverings | Good locality; region coverings for arbitrary shapes | More complex library |
| H3 (Uber) | Hexagons, plus 12 pentagons | Multi-resolution | All six neighbours are equidistant; good for aggregation and pricing zones | Children do not exactly tile their parent |
| R-tree / GiST (PostGIS) | Bounding boxes | Yes | Native SQL; exact ST_DWithin queries with index support | Scaling writes means sharding the database yourself |
Static places vs moving objects
Yelp-style place search is read-heavy and changes slowly, so cache the results for each cell for minutes. Driver search is write-heavy and every result is stale within seconds. Expire positions that have not been refreshed recently (for example after 30 s), so a phone that goes offline does not keep appearing as an available driver.