Case: GitLab's Database Incident
On January 31, 2017, GitLab suffered a major incident that resulted in the deletion of production database data. Service returned the next day using an older copy, leaving about six hours of database changes unrecovered. The postmortem is a vital lesson in operations, fatigue, and backup strategies.
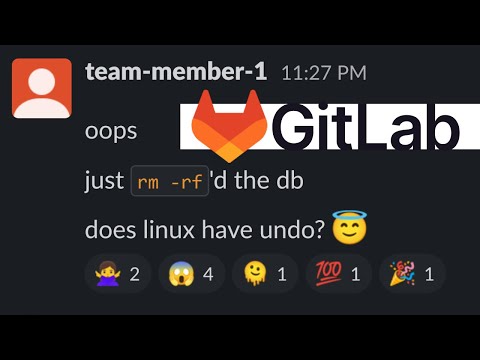
The incident wasn't caused by a malicious hacker or a complex software bug; it was a cascading series of operational failures, exacerbated by human fatigue, culminating in an engineer accidentally running rm -rf on the primary production database instead of a misbehaving replica.
The Anatomy of the Outage
GitLab was experiencing high load caused by spam accounts, causing the PostgreSQL primary database to struggle. A secondary replication node fell far behind. An engineer decided to wipe the lagging secondary node and restart the replication process from scratch.
The engineer opened multiple terminal windows. Due to exhaustion (it was late at night) and identical terminal prompts, the engineer typed rm -rf /var/opt/gitlab/postgresql/data in the terminal connected to the primary production node, not the secondary node.
They realized the mistake seconds later and hit Ctrl+C. The production directory was roughly 300GB, and by the time the command was stopped around 300GB had already been removed (only about 4.5GB was left), so recovery had to use an older copy.
The Backup Failures
Accidental deletions happen. This is why we have backups. But when GitLab tried to restore from backups, they discovered a catastrophic truth: of their five backup and replication safety nets, most had silently failed or were not in use, and the only usable copy was a manual LVM snapshot taken by chance.
- Automated pg_dump: The cron job was failing silently because it was using an incompatible version of pg_dump.
- Azure Disk Snapshots: These were not enabled for the database servers.
- LVM Snapshots: Taken only once every 24 hours; the copy that saved them was a manual snapshot an engineer happened to take about six hours earlier to refresh staging.
- Streaming Replication: Fragile and poorly documented; the lagging replica was the very thing being rebuilt when the deletion happened.
- S3 Backups: The S3 bucket where backups were supposedly being sent was empty.
They eventually restored the database using a manual LVM snapshot of the production database taken about six hours earlier and loaded into the staging environment for load testing; copying it back from staging took around 18 hours. Six hours of user data (issues, merge requests, comments) was permanently lost.
The Lessons Learned
The incident highlighted the stark difference between "having backups" and "having a tested recovery process". Data doesn't exist unless it has been successfully restored.
It also brought attention to operability. Production systems must have safeguards against human error, visual indicators of which environment a terminal is connected to, and blameless postmortem cultures. GitLab famously live-streamed their entire recovery process on YouTube, setting a new standard for transparency in the industry.
Timeline (from GitLab's postmortem, times UTC)
| When | Event |
|---|---|
| 31 Jan, evening | Spam and a background hard-delete job load the primary (db1); the secondary (db2) falls too far behind and WAL segments it needs have already been removed |
| About 17:20 | An engineer takes a manual LVM snapshot of production to load staging, which later becomes the only usable copy |
| About 23:00 to 23:27 | While trying to reseed db2 with pg_basebackup, an engineer runs rm -rf on the data directory in a session connected to db1; it is stopped, but of around 300 GB only about 4.5 GB remain |
| Following hours | Team discovers the backups are unusable and copies the staging snapshot back to production over slow cloud disks |
| 1 Feb, about 18:00 | GitLab.com is back online with data as of about 17:20 the previous day |
Database data from roughly six hours was lost, which GitLab estimated at about 5,000 projects, 5,000 comments and 700 new user accounts. Git repositories and wikis themselves were not lost, though some were orphaned from their database records.
What each safety net actually did
| Mechanism | Status in the incident |
|---|---|
| pg_dump to S3 | Failing silently: it ran a PostgreSQL 9.2 binary against a 9.6 server, and failure emails were rejected by DMARC |
| S3 bucket | Empty, because the dumps never succeeded |
| Azure disk snapshots | Enabled for the NFS server but not for the database servers |
| LVM snapshots | Taken only every 24 hours; the manual one from 17:20 saved the day by luck |
| Streaming replication | Fragile and poorly documented; the replica was the thing being rebuilt |
Turning it into practice
- Restore drills: automatically restore the latest backup to a scratch host on a schedule and run sanity queries; page when it fails.
- Point-in-time recovery: continuous WAL archiving (for example WAL-E or WAL-G, which GitLab adopted) lets you recover to the minute before a mistake.
- Guard rails: different prompt colors for production, confirmation for destructive commands, and delayed deletion (move aside, delete later).
- Measure RPO and RTO: GitLab's restore took around 18 hours partly because of slow disk throughput, something only a rehearsal would have revealed.