Random Sampling Over Infinite Streams
Suppose you have a continuing stream of log events and want to retain 1,000 items as a uniform sample of the finite prefix observed so far. There is no uniform sample over a completed infinite population; the guarantee is evaluated at each current count N.
The Reservoir Sampling Algorithm
Reservoir Sampling is an elegant algorithmic solution to this problem.
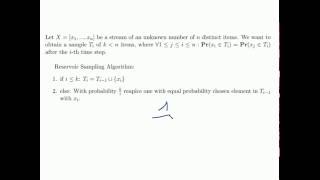
- Create a "reservoir" array of size K (e.g., 1000).
- Fill the array with the first K elements of the stream.
- For every subsequent element at index
i(wherei > K), generate a random numberjbetween 1 andi. - If
j <= K, replace the element at indexjin the reservoir with the new element. Otherwise, discard the new element.
Why it works
Through inductive mathematical proof, this algorithm guarantees that at any point in time, every element seen so far has an equal probability (K/N) of being in the reservoir. It requires only O(K) memory and O(N) time (a single pass through the stream).
A retained reservoir differs from independent head sampling that immediately keeps roughly 1% of traces: later arrivals can replace earlier reservoir members. Combining worker reservoirs also requires each worker's original population size; choosing equally from equal-sized local samples biases small partitions. Use a weighted merge algorithm or sample from a globally keyed priority, and record the randomization/version needed for reproducibility.
Worked example: K = 2 over a, b, c
- After a and b, the reservoir is [a, b].
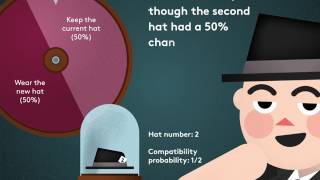
- c arrives as item 3; it is kept with probability 2 out of 3, replacing a or b with equal chance.
- Probability that a survives = probability c is rejected (1/3) plus probability c is kept and replaces b (2/3 x 1/2) = 1/3 + 1/3 = 2/3.
- Probability that c is in the reservoir = 2/3. All three items have probability 2/3 = K divided by N. Uniform.
Worked example: merging two workers correctly
Worker 1 saw 900,000 events, worker 2 saw 100,000, each kept a reservoir of 1,000. For a merged sample of 1,000, each slot should come from worker 1 with probability 0.9 and worker 2 with probability 0.1, drawn without replacement from each reservoir. Taking 500 from each would over-represent worker 2's events by a factor of 5. Alternatively, give every event a random key and keep the K smallest keys globally (bottom-K sampling), which merges trivially by taking the K smallest of the union.
Variants
| Algorithm | What it adds | Cost |
|---|---|---|
| Algorithm R (Vitter) | Uniform sample of K | One random number per item |
| Algorithm L (Li, 1994) | Computes how many items to skip before the next replacement | Far fewer random numbers for long streams |
| Weighted, A-Res (Efraimidis and Spirakis) | Item kept with probability proportional to weight: key = u to the power 1/w, keep the K largest keys | A heap of size K |
| Bottom-K with hashed keys | Deterministic, reproducible, trivially mergeable | Needs a good hash; sample depends on key choice |
Where it is used
Distributed tracing systems use tail-based sampling that holds recent traces and keeps a bounded, representative subset, often combined with rules that always keep errors and slow requests. Metrics libraries such as Dropwizard Metrics used exponentially decaying reservoirs to estimate latency histograms. Databases use reservoir-style sampling to build column statistics for query planners without a full scan.