Under the Hood: Binary Serialization & Disk Layout
Text formats such as JSON and CSV favor inspectability and interoperability, but parsing and locating individual records can cost more CPU and I/O than a purpose-built representation. When measurements justify that tradeoff, a storage engine can use a versioned binary format with explicit record boundaries and validation.
Physical Record Binary Memory Layout
Header Specification & Hardware Alignment
1. File Header (Magic Bytes & Metadata)
One possible format starts with a fixed-size header block:
- Magic Bytes (4 Bytes): A unique signature (e.g.
0x53444231for "SDB1") verifying that the file is indeed a valid database file. - Format Version (2 Bytes): Allows future database upgrades to read older file formats or migrate them on the fly.
- Block Size (2 Bytes): Defines page size alignment (e.g. 4096 bytes or 16384 bytes).
- Endianness Marker (2 Bytes): Resolves Little-Endian vs Big-Endian integer encoding differences across CPU architectures.
2. The 4KB Memory Alignment Rule
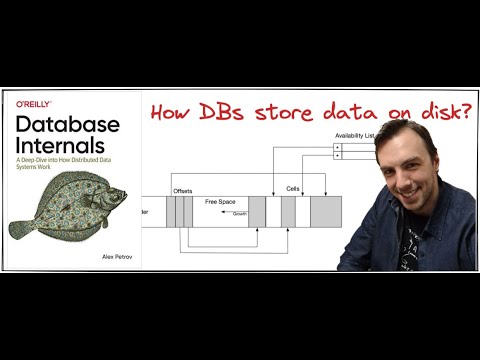
Filesystems and devices expose different logical blocks, physical sectors, pages, and direct-I/O alignment constraints. Packing records into blocks can bound the number of reads and simplify checksums, but padding every record may waste space. Choose and record the block size from the actual I/O contract rather than assuming a universal 4KB rule.
Worked example: one record, byte by byte
A simple length-prefixed record format (this is essentially Bitcask's layout):
| Field | Size | Example value |
|---|---|---|
| CRC32C over the rest of the record | 4 B | computed last |
| Timestamp (ms, little-endian) | 8 B | 1,790,000,000,000 |
| Key length | 4 B | 7 |
| Value length | 4 B | 100 |
| Key bytes | 7 B | user:42 |
| Value bytes | 100 B | payload |
Total 127 bytes, with 20 bytes of fixed header. To read the record at offset 4096, read 20 bytes, check that 4096 + 20 + 7 + 100 does not exceed the file size, read the remaining 107 bytes, recompute the CRC and compare. If a crash truncated the file mid-record, the length check or CRC fails and recovery truncates the file back to 4096.
Choosing a representation
| Format | Seek to record N | Parse cost | Schema evolution | Debuggability |
|---|---|---|---|---|
| JSON lines | Scan, or keep a side index | High (text parsing) | Easy, loose | Excellent |
| Length-prefixed binary with CRC | Offset index gives one read | Very low | Needs a version field | Needs a dump tool |
| Protobuf or FlatBuffers records | Needs framing plus index | Low (FlatBuffers near zero-copy) | Strong field-number rules | Tooling available |
| Fixed-width slotted pages | Page id times page size | Very low | Harder | Needs tooling |
How real formats do it
- SQLite: a 100-byte file header beginning with the string
SQLite format 3, including page size and format version numbers. - LevelDB/RocksDB WAL: 32 KB blocks; each record fragment has a 7-byte header (checksum, length, type) with types FULL, FIRST, MIDDLE and LAST so records can span blocks and a torn block is detectable.
- Parquet: the magic
PAR1at both ends, with the metadata footer at the end so a writer can stream data first and a reader can find the footer with one small read from the tail.